A schema-enforced large language model framework produces largely reproducible decision codes in simulated sarcoma tumor boards - Nature
A new framework for large language models (LLMs) has demonstrated its ability to produce largely reproducible decision codes in simulated sarcoma tumor boards. The research, published in Nature, indicates that schema enforcement can contribute to consistency in AI-assisted medical decision-making simulations.
The study introduces a method where LLMs generate medical decision codes within a schema-enforced framework. This structure aims to guide the model's output, moving beyond free-form text generation to produce structured, consistent data points. The focus on reproducibility suggests an effort to address a key challenge in AI applications, particularly in sensitive fields like healthcare, where variability in outcomes can undermine trust and utility.
Reproducibility in this context means that given similar inputs, the LLM framework consistently generates similar decision codes. This is important because it implies a level of reliability that could be critical for integrating AI into clinical workflows. If an AI system cannot consistently arrive at comparable conclusions when presented with similar patient scenarios, its practical value for aiding human experts diminishes.
The use of simulated tumor boards highlights the controlled environment of the research. While promising for demonstrating the framework's capabilities, the transition from simulation to real-world clinical application involves navigating complex variables not fully captured in a controlled setting. The findings establish what is possible under specific conditions, rather than immediately proving widespread clinical utility or generalizability across diverse medical contexts.
This work establishes a step towards making AI outputs more predictable and verifiable in specific medical applications. For developers and practitioners in Asia exploring AI for healthcare, it suggests that structured input and output mechanisms, rather than just raw model power, can be crucial for achieving practical, trustworthy results. The emphasis remains on the framework's design rather than the inherent intelligence of the LLM itself.
Share this article
Related reading
6 stories
The Sequence Radar - Issue 948: Last Week in AI: Billions in Funding, Hundreds of Papers, One Big Leap?
Our weekly AI roundup often tracks the latest research and breakthroughs in large language models.
Anthropic's IPO bank closed position meant to stabilize stock, removing source of support
Apple develops Mac AI agent, plans third-party control safeguards - TechGig
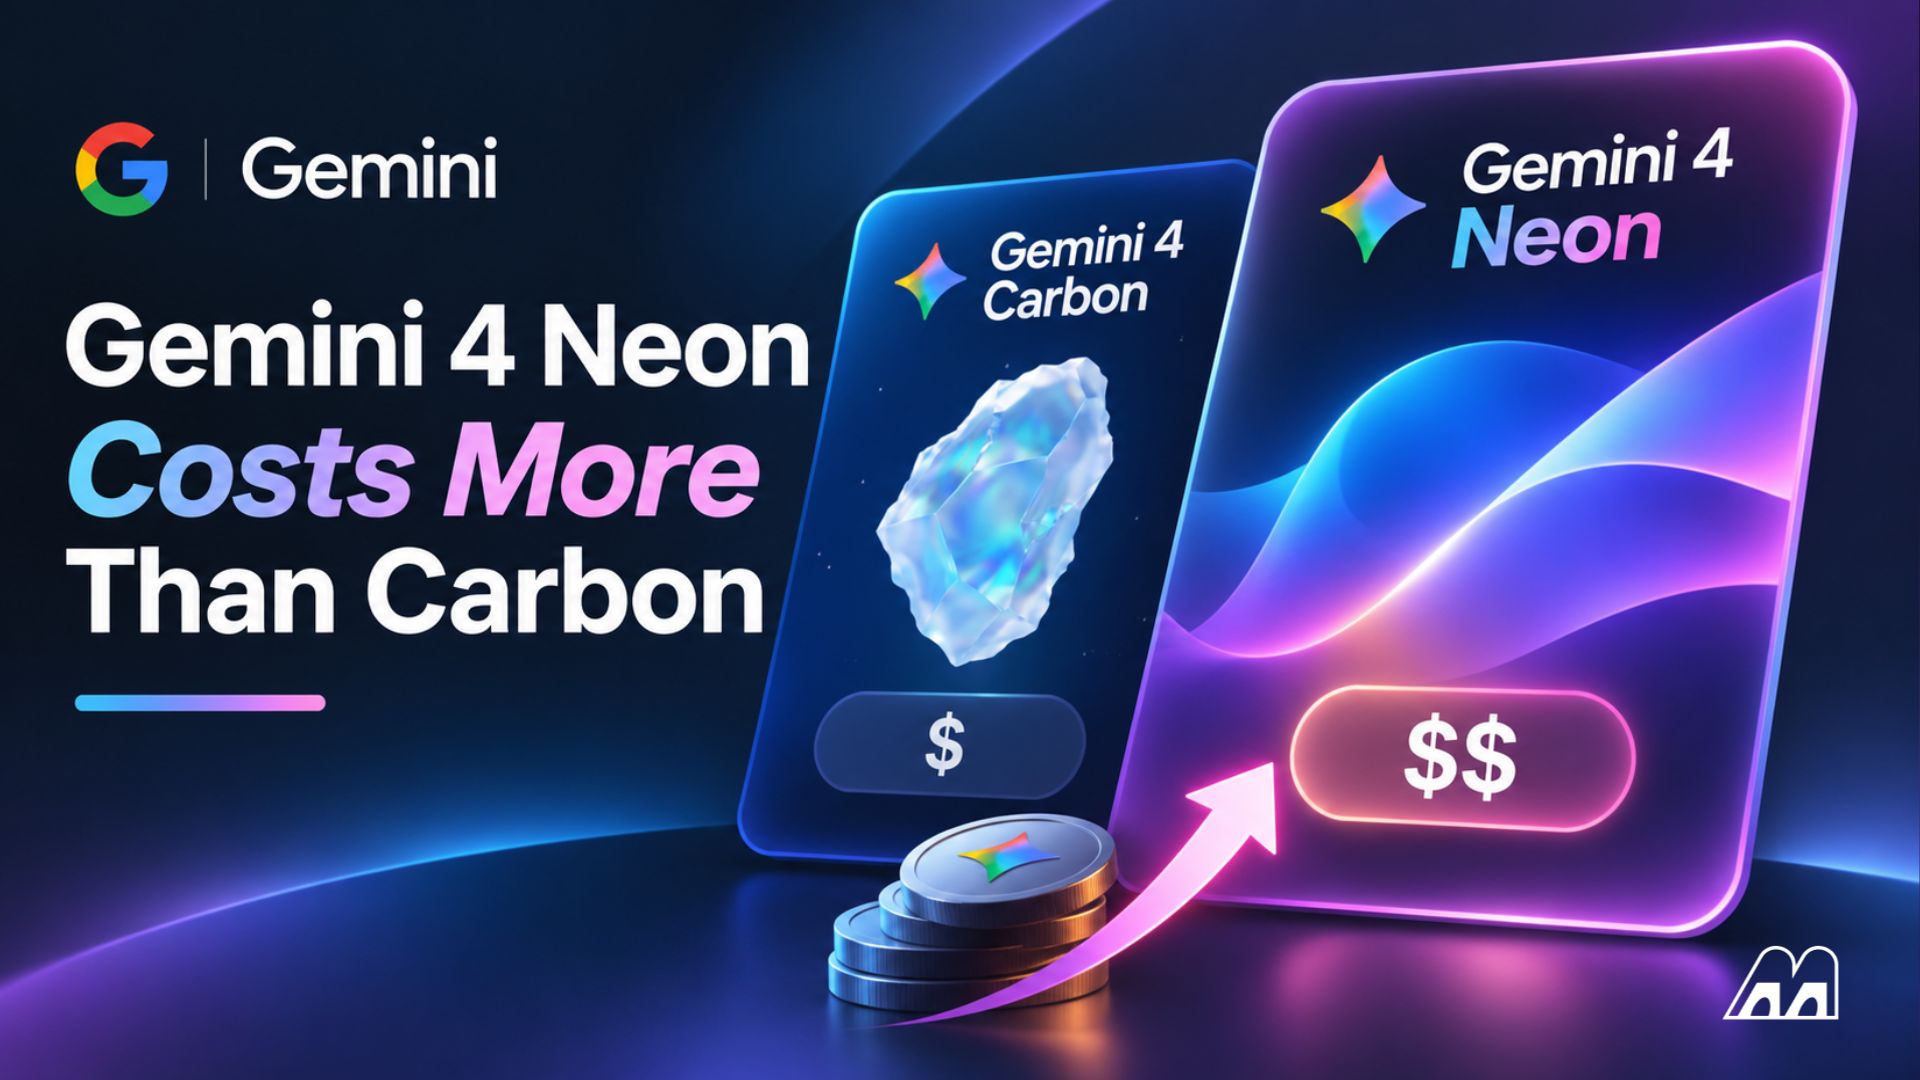
Gemini 4 Neon Costs More Than Carbon Until December 1. Here’s Which Gemini Model You Should Actually Use

How to deploy an app you built with AI to your own server