Intel squeezed a 1.58-bit LLM down to 1.485 bits without changing a single weight
Intel researchers developed a method to reduce the bit size of a large language model (LLM) without altering its weights. They compressed a 1.58-bit ternary model down to 1.485 bits. This optimization improves efficiency by reducing the model's memory footprint. The technique focuses on post-training quantization, making models smaller for deployment.
Intel’s compression of a 1.58-bit LLM to 1.485 bits shows a clear path to more efficient AI. The key is not changing weights but optimizing post-training quantization. This method reduces memory demands, which is crucial for deploying large models on less powerful hardware. It moves beyond theoretical limits, making practical application a nearer reality.
This advance directly benefits Asian AI developers targeting edge devices and mobile platforms. Companies in markets like South Korea and Japan, focused on integrating AI into consumer electronics, gain a significant advantage. Smaller models mean lower inference costs and faster processing on local hardware. This could accelerate the adoption of on-device AI in these competitive markets.
The thing to watch is how quickly this technique moves from research to commercial implementation. If Intel can integrate this into its AI chip offerings by late 2027, it would give them a strong competitive edge. This would also pressure Asian chipmakers to develop similar or superior post-quantization methods for their own AI accelerators.
Related reading
6 stories
China to see major shift to Huawei for AI model training in 2027: rotating chair
Huawei's Atlas 960E superpod and its role in AI model training highlights the hardware side of AI efficiency.
Will AI adoption shrink office space? Asia-Pacific firms are on the fence in survey
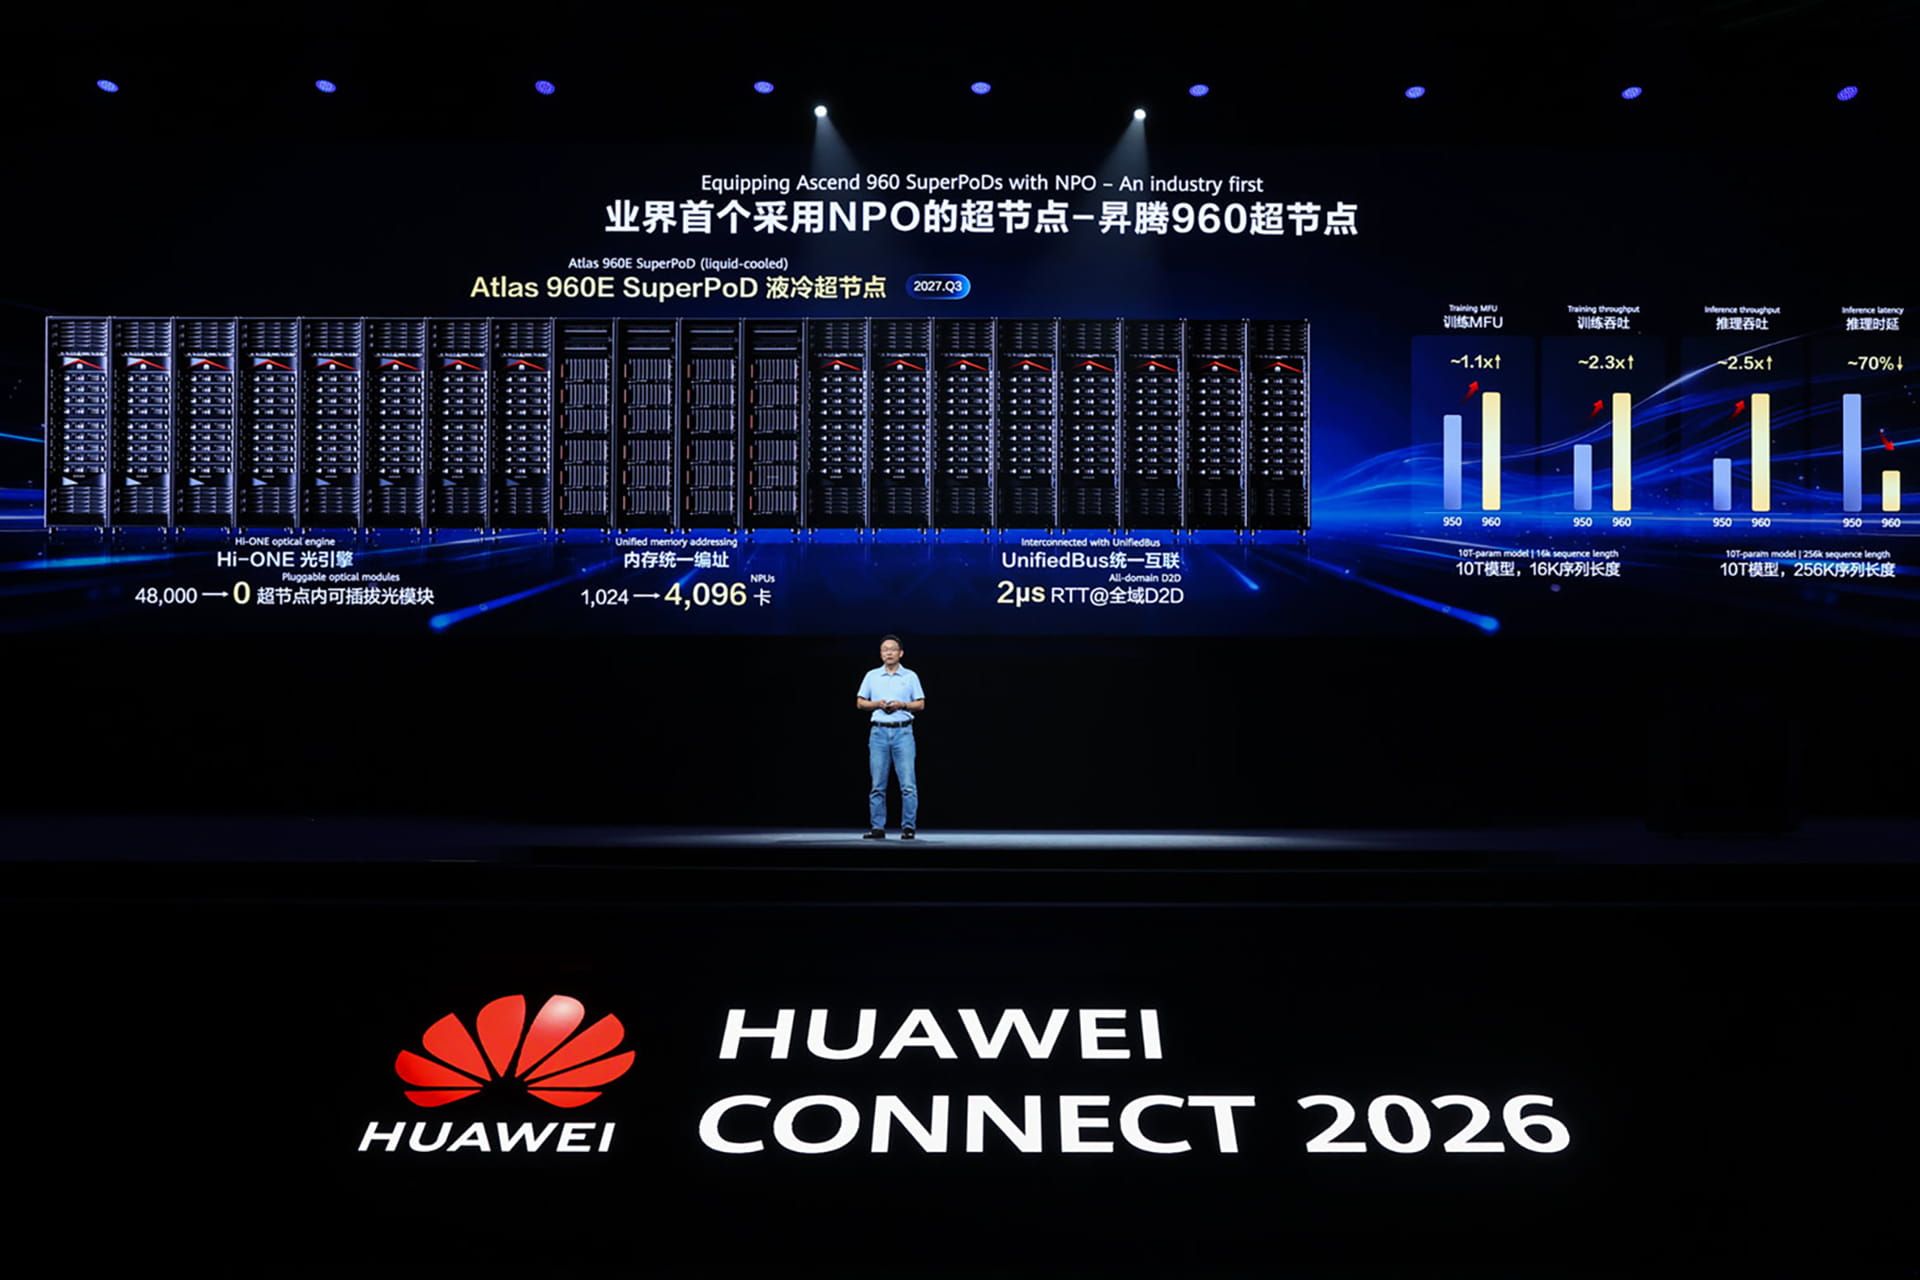
Huawei brings near-packaged optics to AI with Atlas 960E superpod
Chip foundries better insulated in an AI slowdown than Asia-Pacific tech peers, S&P says

OCBC Extends Bank of Ningbo Partnership as 20 Percent Shareholder